
Data engineering and analytics
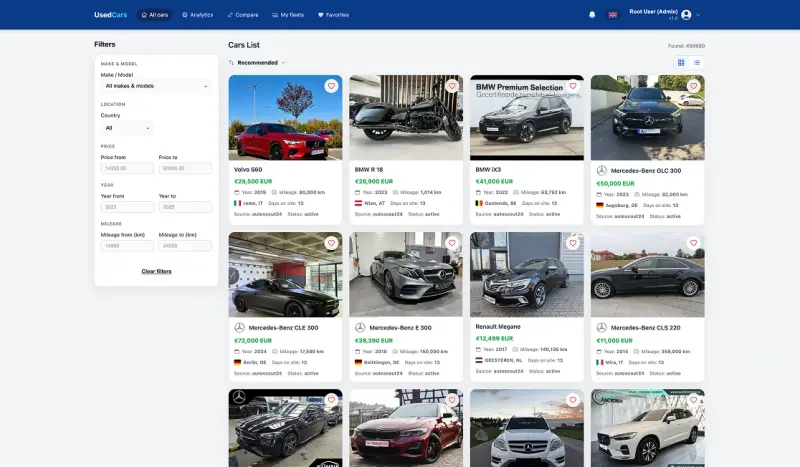
Pipelines, storage and dashboards that turn scattered data into numbers you can trust. Our market analytics platform has processed 1M+ listings.
01 — What we do
Data engineering and analytics services we provide
- 01
Data pipeline design & ETL
We design and build extract, transform, load pipelines that move data reliably from source systems into a structure your application and analytics layer can use.
- 02
Real-time data ingestion & processing
We build ingestion pipelines that process data as it arrives, so dashboards and pricing logic reflect current conditions instead of yesterday's batch job.
- 03
Data aggregation from multiple sources
We connect and normalize data from different external sources, feeds, and regional markets into one consistent dataset.
- 04
Analytics dashboards & reporting
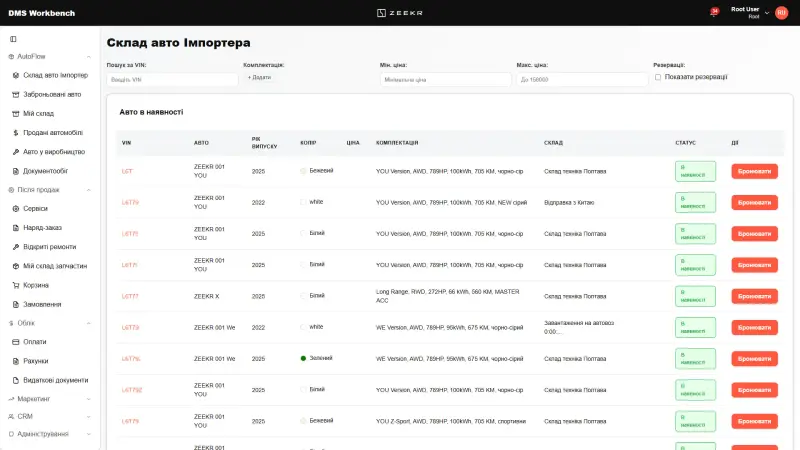
We build the reporting layer on top of the pipeline, from operational dashboards to the metrics a business team checks daily.
- 05
Database design for analytics workloads
We design schemas and storage that hold up under analytical queries, not just transactional ones, so reporting stays fast as data grows.
- 06
Data quality & monitoring
We build validation checks and monitoring into the pipeline itself, so bad data gets caught before it reaches a dashboard or a pricing decision.
02 — When
When companies come to us for data engineering
Data is spread across systems with no unified view. Listings, transactions, or product data sit in separate tools and databases, and nobody can answer a simple cross-system question without manual exports.
Manual spreadsheet reporting can't keep up. Teams need real-time analytics instead of a weekly export someone stitches together by hand, especially when pricing or inventory changes by the hour.
An existing dashboard or reporting tool has hit its ceiling. The reporting layer was fine at a smaller scale, but query times, data volume, or update frequency have outgrown it.
Multiple external sources need to be aggregated and normalized. Data arrives from different markets, partners, or APIs in different formats, and it needs a consistent structure before anyone can analyze it.
04 — Process
Our data engineering process
- 01
Data source audit
We map every system, feed, and external source that needs to feed the pipeline, and identify gaps in format, frequency, or reliability.
- 02
Pipeline architecture design
We design the ingestion, transformation, and storage layers, including how real-time and batch data flow together.
- 03
Development
We build the pipeline, database schema, and integration points, working in short cycles so you can review progress along the way.
- 04
Validation & quality checks
We build automated checks into the pipeline so data errors, duplicates, or gaps are caught before they reach reporting.
- 05
Dashboard & reporting layer
We build the analytics views and dashboards your team actually uses, tied directly to the validated data.
- 06
Ongoing monitoring
We set up monitoring and alerting so pipeline failures or data anomalies get flagged immediately, not discovered weeks later.
05 — Frequently asked questions
Frequently asked questions
We build the infrastructure that moves data from its source into a form your product or team can use: pipelines, databases, and the analytics or reporting layer on top.
06 — Contact
Tell us what you need
We reply with a proposal.